JDBC
Overview Copied
The JDBC (Java Database Connectivity) Collection Agent plugin uses JDBC to gather data from a database by executing user-specified queries.
JDBC drivers Copied
The following JDBC drivers are packaged with the JDBC plugin:
- MariaDB: mariadb-java-client
- PostgreSQL: postgresql
- Oracle: ojdbc11
- MSSQL (SQL Server): mssql-jdbc
A JDBC plugin configured to connect to the databases above will work out of the box.
For databases not listed above, add their corresponding JDBC driver jar file to the classpath when running the collection agent.
- For example, when using a Sybase JDBC driver when running a collection agent as a standalone process, you need to add
/opt/sybase/jConnect-16_0/classes/jconn4.jarin the classpath as shown below.
java -cp /opt/sybase/jConnect-16_0/classes/jconn4.jar:<Netprobe directory>/collection_agent/collection-agent-3.2.2-exec.jar "-Dlogback.configurationFile=<Netprobe directory>/collection_agent/logback.xml" com.itrsgroup.collection.ca.Main "collection-agent-jdbc-sybase.yml"
- For collection agent started by a Netprobe, see JVM args in Managed Collection Agent.
Plugin configuration reference Copied
collectors:
  - name: jdbc
    type: plugin
    className: JdbcCollector

    # Interval (in millis) between query execution (optional, defaults to 1 minute)
    collectionInterval: 60000

    # Number of worker threads (i.e. concurrent query executors).
    # Default value shown. With Kerberos, this also sets the Hikari maximumPoolSize
    # unless connection.propertiesFile explicitly sets maximumPoolSize.
    workerThreads: 1

    connection:
      # The JDBC Url which identifies the database to connect to
      # With kerberos: omit auth credentials from the URL (user/password and driver Kerberos flags).
      # Non-auth params such as sslmode or encrypt are allowed.
      url: jdbc:mysql://localhost:5005/geneos_db

      # Username used to connect to the database, or Kerberos principal
      # (e.g. dbuser@REALM.COM) when kerberos is set
      user: <database user>

      # Password of the said username. Omit when using Kerberos.
      password: <database password>

      # Properties file which contains connection properties. For debugging purposes/advanced users only.
      # Do not include a password when using Kerberos.
      propertiesFile: <filename of properties file>

      # Kerberos (GSSAPI) authentication (optional). Driver support is selected from the JDBC URL.
      # Omit this block entirely for standard username/password authentication.
      kerberos:
        # Path to a keytab file for the principal. (optional, mutually exclusive with ccachePath)
        # Not used for Oracle Thin — use ccachePath after kinit instead.
        keytabPath: /path/to/dbuser.keytab

        # Path to a Kerberos credential cache file. Must be a plain filesystem path.
        # (optional, mutually exclusive with keytabPath)
        # Preferred for Oracle Thin.
        ccachePath: /path/to/krb5cc_file

    # Array of query configurations. Multiple queries can be specified.
    queryConfigs:
        # Mandatory. Query to run
      - query: "show processlist"

        # Mandatory. Unique identifier of this query. This will be used in logs and signal events.
        name: "Process List"

        # Mandatory. Dimensions added to each datapoint. At least one dimension is required from either dbColumns or static key-value pairs.
        # Dimensions common to all queries defined can be configured under the commonQueryConfig section.
        dimensions:

          # List of DB columns to use as datapoint dimensions.
          dbColumns:
            - Id
            - User
            - Host
            - db

          # Map of static key-value pairs that will be added as a dimension to each datapoint.
          static:
            queryAlias: "Process List"

        # List of DB columns that will be added as datapoints
        dataPoints:
            # Column Name
          - column: Command
            # DataPoint type. Possible values: StatusMetric, Gauge, Counter, EntityAttribute
            type: EntityAttribute

          - column: Time
            type: Gauge
            # unit parameter is only applicable to gauge.
            # Possible values are as described in Unit class.
            unit: seconds

          - column: State
            type: StatusMetric

          - column: Info
            type: EntityAttribute

        # Columns that are not specified in the dimensions or datapoints config will be treated as a datapoint.
        # If the SQL data is of numeric SQL type, it will be treated as a Gauge by default.
        # If it is a Date, Time, or Timestamp type, it will be treated as an EntityAttribute.
        # Otherwise, it will be treated as a StatusMetric.

    # Common query configuration that will be applied to all queries defined in queryConfigs.
    # These configurations can also be placed inside a specific query configuration.
    # The query-specific configuration overrides the common config below 2 configs are the same.
    commonQueryConfig:
        # Query timeout in seconds. Default is no timeout.
        timeout: 5

        # The timezone offset used to process TIMESTAMP (without time zone) data. Default is "+00:00" or UTC.
        timestampZoneOffset: "+08:00"

        dimensions:
            dbColumns:
              - ID
            static:
                urlAlias: "LocalHost:5005 geneos_db"
        dataPoints:
            - column: comment
              type: EntityAttribute
Translation of database result set to datapoints Copied
You must specify how to translate the data returned by the query into datapoints in each query-configuration section.
For example, the query in the example configuration above returns the result set below:
mysql> show processlist;
+----+-------------+-----------------+-----------+---------+------+----------+------------------+
| Id | User        | Host            | db        | Command | Time | State    | Info             |
+----+-------------+-----------------+-----------+---------+------+----------+------------------+
|  7 | geneos_user | localhost:51558 | geneos_db | Query   |    0 | starting | show processlist |
|  8 | geneos_user | localhost:54952 | geneos_db | Sleep   |    3 |          | NULL             |
+----+-------------+-----------------+-----------+---------+------+----------+------------------+
2 rows in set (0.00 sec)
The configuration above specifies the following:
- The
Id,User,Host, anddbcolumns are dimensions. - The
queryAliasandurlAliasare static dimensions, which will be added to each datapoint. - The columns to be used as datapoints, and their corresponding data type. For example, the
Commandcolumn is an EntityAttribute and theTimecolumn is a Gauge with unit inseconds.
With the configuration above, the first datapoint in the first row will be the Command column,
which you must define as an EntityAttribute datapoint type.
The datapoint will then contain the following:
- name =
Command - value =
Query - dimensions:
- Id =
7 - User =
geneos_user - Host =
localhost:51558 - db =
geneos_db - urlAlias =
LocalHost:5005 geneos_db - queryAlias =
Process List
- Id =
Dimension ordering and precedence Copied
When dimensions are configured at both the commonQueryConfig level and individual queryConfig level, they are merged with specific ordering and precedence rules to ensure consistent dimension handling.
Dimension ordering Copied
Dimensions are applied to datapoints in the following order:
- Common Query Config: Static Dimensions — static key-value pairs defined in
commonQueryConfig.dimensions.static, following the order specified in the configuration. - Query Config: Static Dimensions — static key-value pairs defined in
queryConfig.dimensions.static, following the order specified in the configuration. - Common Query Config: DB Column Dimensions — database columns defined in
commonQueryConfig.dimensions.dbColumns, following the order specified in the configuration. - Query Config: DB Column Dimensions — database columns defined in
queryConfig.dimensions.dbColumns, following the order specified in the configuration.
This ordering is preserved using SequencedMap collections to maintain consistent dimension key ordering across all datapoints.
Note
Dimensions within each category appear in the exact order defined in your configuration. For a specific dimension ordering, list the static dimensions and DB columns in your desired sequence.
Value precedence Copied
When the same dimension key is defined in both common and individual query configurations, the query-specific value takes precedence:
- Static dimensions — if the same static dimension key exists in both
commonQueryConfig.dimensions.staticandqueryConfig.dimensions.static, the value from the individual query config is used. - DB column dimensions — if the same database column is specified in both
commonQueryConfig.dimensions.dbColumnsandqueryConfig.dimensions.dbColumns, the column appears only once in the final dimension list and is not duplicated.
Configuration example Copied
Given this configuration:
commonQueryConfig:
  dimensions:
    static:
      environment: "production"   # 1st: First static dimension in common config
      region: "us-east-1"         # 2nd: Second static dimension in common config
    dbColumns:
      - server_id                 # 3rd: First DB column in common config
      - database_name             # 4th: Second DB column in common config

queryConfigs:
  - query: "SELECT * FROM processes"
    dimensions:
      static:
        region: "us-west-2"       # Overrides common config value, keeps position #2
        service: "web-api"        # 5th: First static dimension in query config
      dbColumns:
        - process_id              # 6th: First DB column in query config
        - user_name               # 7th: Second DB column in query config
The resulting dimension order for each datapoint would be:
| Order | Dimension | Ordering rule |
|---|---|---|
| 1 | environment = “production” |
The first static dimension under commonQueryConfig was used, following the dimension ordering. |
| 2 | region = “us-west-2” |
The second static dimension under commonQueryConfig was used, but the value from queryConfigs takes precedence. |
| 3 | service = “web-api” |
The first query static under commonQueryConfig was used, following the dimension ordering. |
| 4 | server_id = [value from DB] |
The first DB column under commonQueryConfig was used, following the dimension ordering. |
| 5 | database_name = [value from DB] |
The second common DB column under queryConfigs was used, following the dimension ordering. |
| 6 | process_id = [value from DB] |
The first DB column under queryConfigs was used, following the dimension ordering. |
| 7 | user_name = [value from DB] |
The second DB column under queryConfigs was used, following the dimension ordering. |
This predictable ordering ensures that dimension keys appear in the same sequence across all datapoints for consistent metric aggregation and visualization.
Handling of invalid data Copied
Dimension values should never be null or empty. If the value of any of the dimensions is null or empty, the datapoints in that row will be ignored. If the value of a datapoint column is null or empty, that datapoint will be ignored.
Timestamp processing Copied
SQL has two timestamp types:
TIMESTAMP- no timezone. The timestampZoneOffset configuration set in the query configuration will be used to convert the timestamp into UTC. If no timestampZoneOffset configuration is set, the data is treated as date-time in UTC.TIMESTAMP WITH TIME ZONE
By default, timestamp data types are published as EntityAttribute. However, it is also possible to specify it as a gauge or counter. In such cases, the unit will automatically be set to EPOCH_MILLISECONDS.
Properties file Copied
The connection: propertiesFile: configuration can be used to specify a file containing database-specific configurations.
To specify database-specific properties, define one property per line in the file with the following format:
`dataSource.<property name>=<property value>`
For example, to add TLS support for MySQL, the following MySQL-specific properties should be added to the connection: propertiesFile: configuration:
dataSource.sslMode=VERIFY_IDENTITY
dataSource.trustCertificateKeyStoreUrl=file:///home/mysql/certs/catruststore
dataSource.trustCertificateKeyStorePassword=mypassword
dataSource.clientCertificateKeyStoreUrl=file:///home/mysql/certs/keystore
dataSource.clientCertificateKeyStoreType=PKCS12
dataSource.clientCertificateKeyStorePassword=mypassword
Other database-specific JDBC drivers may also have their own set of properties.
You can specify TLS, SPN, and other non-authentication driver settings in the URL or in propertiesFile. Do not include a password when you use Kerberos.
Connecting with Kerberos (GSSAPI) Copied
To enable Kerberos, add a connection.kerberos block and set connection.user to the Kerberos principal. Use the user@REALM form. The plugin selects the driver mechanism from the JDBC URL prefix. Omit connection.password when Kerberos is enabled.
Supported JDBC URL prefixes Copied
| JDBC URL prefix | Bundled driver |
|---|---|
jdbc:postgresql: |
PostgreSQL (also used for CockroachDB) |
jdbc:sqlserver: |
Microsoft JDBC Driver |
jdbc:oracle: |
Oracle Thin (ojdbc11) |
jdbc:mariadb: or jdbc:mysql: |
MariaDB Connector/J |
Unsupported URL prefixes are rejected at configure time.
This example shows a Kerberos connection:
connection:
  url: jdbc:postgresql://db.example.local:5432/mydb
  user: dbuser@EXAMPLE.COM
  kerberos:
    keytabPath: /path/to/dbuser.keytab
Authentication modes Copied
You do not need an external Java Authentication and Authorization Service (JAAS) file. The plugin logs in with Krb5LoginModule and opens JDBC connections under the resulting subject.
| Mode | How to configure | Credential source |
|---|---|---|
| Keytab | Set kerberos.keytabPath |
The plugin logs in with the keytab. You do not need to run kinit first. This mode is not used for Oracle Thin. |
| Credential cache (explicit path) | Set kerberos.ccachePath |
The plugin reads the ticket-granting ticket (TGT) from that cache file. This mode is preferred for Oracle Thin. |
| Credential cache (system default) | Set kerberos: {} |
Uses KRB5CCNAME or the OS default cache. |
Note
keytabPathandccachePathare mutually exclusive.ccachePathmust be a plain file system path (for example,/tmp/krb5cc_1000). Do not use aTYPE:prefix such asFILE:,DIR:, orKCM:. For caches that are not files, usekerberos: {}and setKRB5CCNAMEon the Collection Agent JVM.- When the collector starts, it runs a Kerberos preflight login. A bad keytab, an unreachable Key Distribution Center (KDC), or a wrong principal fails immediately. Issues with the database SPN or grants appear on the first database connection.
- Do not set
connection.passwordor a password inpropertiesFilewhen Kerberos is enabled.
Kerberos JDBC URL policy Copied
When Kerberos is enabled, the plugin handles authentication through JDBC properties and a JAAS subject. It rejects authentication credentials and related settings in the JDBC URL when you configure it, so those settings cannot mix with the plugin authentication path. URL parameters that are not used for authentication, such as sslmode, encrypt, options, and SPN helpers, remain allowed on every supported driver. The plugin does not set SSL. The disallowed parameters differ by driver because URL syntax and the precedence of URL settings versus properties differ.
Driver-specific defaults Copied
The plugin applies these JDBC properties when you enable Kerberos and they are not already set in the URL or propertiesFile. You do not need to set them unless you want to override the defaults.
PostgreSQL and CockroachDB Copied
JDBC URL prefix: jdbc:postgresql:
- JDBC
useris the principal without the@REALMsuffix. - Sets
jaasLogin=falseandgsslib=gssapi. - When Kerberos is enabled, the URL must not contain
user,password,jaasLogin, orgsslib. Set the principal inconnection.user, omit passwords, and usepropertiesFileonly to override thejaasLoginandgsslibdefaults. URL parameters that are not used for authentication, such assslmodeandoptions, are allowed. - Optional:
kerberosServerName,sslmode, orgssEncMode.
SQL Server Copied
JDBC URL prefix: jdbc:sqlserver:
- Sets
integratedSecurity=trueandauthenticationScheme=JavaKerberos. useris the full Kerberos principal.- When Kerberos is enabled, the URL must not contain
password. The URL can still includeuser,integratedSecurity,authenticationScheme, and TLS settings such asencrypt. - Optional:
serverSpnif the default SPN cannot be derived from the host.
Oracle Thin Copied
JDBC URL prefix: jdbc:oracle:
oracle.net.authentication_services=(KERBEROS5)oracle.net.kerberos5_mutual_authentication=trueoracle.net.kerberos5_cc_namefromkerberos.ccachePath, or fromKRB5CCNAME(FILE:or a plain path) when you usekerberos: {}.- When Kerberos is enabled, the URL must not embed Thin or OCI username and password credentials, and must not contain a user or password in the query string. Query parameters that are not used for authentication are allowed.
- Authenticates only from a file credential cache. Prefer
kerberos.ccachePathafter you runkinit. kerberos.keytabPathis not used for Oracle. Obtain a TGT withkinit -ktand store it in a credential cache first.kerberos: {}works only when the Collection Agent process hasKRB5CCNAMEset to that file cache. Without it, Kerberos is not used.
MariaDB and MySQL-compatible Copied
JDBC URL prefix: jdbc:mariadb: or jdbc:mysql:
- JDBC
useris the principal without the@REALMsuffix. - The server account must use the
gssapiplugin. - When Kerberos is enabled, the URL must not contain
userorpassword. Parameters that are not used for authentication, such assslModeandservicePrincipalName, are allowed. - Optional:
servicePrincipalNameif the SPN differs from the default. - Oracle MySQL Connector/J Kerberos is not bundled. Use MariaDB Connector/J.
Connection pool sizing (Kerberos) Copied
When Kerberos is enabled and propertiesFile does not set maximumPoolSize:
maximumPoolSize=workerThreadsminimumIdle=1(unless you set it inpropertiesFile)
Kerberos configuration file lookup Copied
The JVM looks for krb5.conf in this order:
-Djava.security.krb5.conf=<path>on the Collection Agent JVM (recommended when you are not using the operating system default)<java.home>/conf/security/krb5.conf/etc/krb5.confon Linux or macOS, or%WINDIR%\krb5.inion Windows
krb5.conf is global to the JVM. All Kerberos collectors in the same Collection Agent must share a compatible realm and KDC configuration.
Credential cache location resolution Copied
When ccachePath is not set, the plugin uses:
KRB5CCNAME(for example,FILE:/tmp/krb5cc_1000)- The operating system default (for example,
/tmp/krb5cc_<uid>on Linux)
Example configuration Copied
The following collector configuration runs the show processlist query, which returns a list of all the current processes running on the server.
connection:
  url: jdbc:mariadb://ab1-23-45-678-910.ap-southeast-2.compute.amazonaws.com:1111/geneos_db
  user: admin
  password: password

queryConfigs:
  - query: "show processlist"
    name: "Process List"

    dimensions:
      dbColumns:
        - Id
      static:
        table: "processes"
        database: "Geneos DB"

    dataPoints:
          - column: User
            type: EntityAttribute
          - column: Host
            type: EntityAttribute
          - column: db
            type: EntityAttribute
          - column: Command
            type: EntityAttribute
          - column: Time
            type: Gauge
            unit: seconds
          - column: State
            type: StatusMetric
          - column: Info
            type: EntityAttribute
This query returns a result set like the following:
mysql> show processlist;
+---------+------+------------------------+------------+----------+-------+-----------+------------------+
| Id      | User | Host                   | db         | Command  | Time  | State     | Info             |
+---------+------+------------------------+------------+----------+-------+-----------+------------------+
| 811536  | root | 119.92.192.242:51110   | geneos_db  | Query    | 0     | starting  | show processlist |
+---------+------+------------------------+------------+----------+-------+-----------+------------------+
1 row in set (0.00 sec)
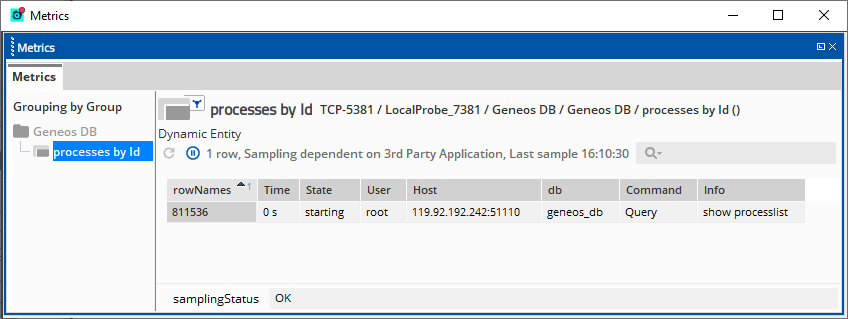
The Id column is defined as a dimension in the example configuration above because it is the unique identifier for each process in the result set. The configuration also defines static dimensions for the table="processes" and database="Geneos DB", which will be added as dimensions to the datapoints. The rest of the data are then treated as datapoints.
As an example, let’s consider the User column. An EntityAttribute type of a datapoint will be created for this column based on the configuration. This data point will have the following fields:
- name = User
- value = root
- dimensions
- Id = 811536
- table = processes
- database = “Geneos DB”
In order to create a Dynamic Entity dataview for this configuration, it is necessary to set up a Dynamic Entity mapping as follows:
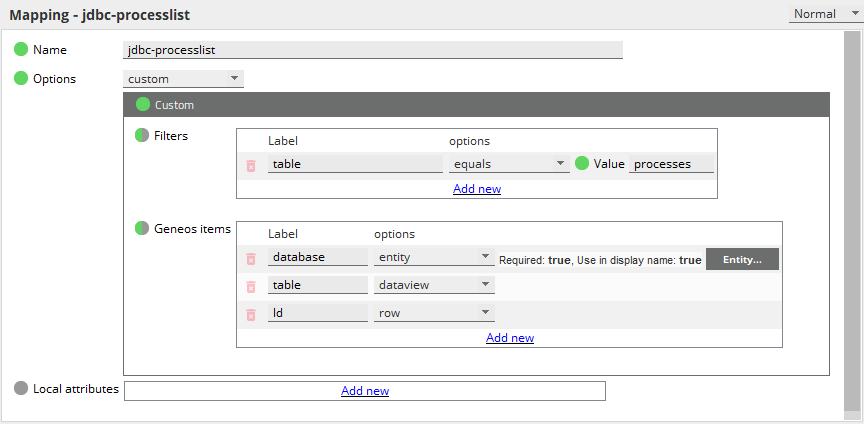
JDBC Dynamic Entity dataview:
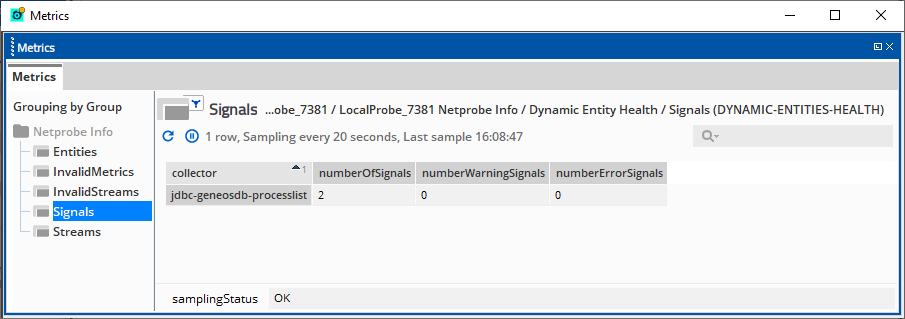
You can also check for errors in the collector by viewing the Netprobe Info > Dynamic Entities Health > Signals self-monitoring dataview. For more information, see Signals in Dynamic Entities Health.
Configure Geneos to deploy the JDBC plugin Copied
The JDBC plugin supports Collection Agent publication into Geneos using Dynamic Managed Entities. To set up the plugin in Geneos:
- Set up the JDBC Collection Agent plugin.
- Configure your mappings.
- Configure other Dynamic Entities in the Gateway. For a more detailed procedure, see Create Dynamic Entities in Collection Agent setup.
Set up the JDBC Collection Agent plugin Copied
Use one of the following options to configure the plugin:
- Set up your collector in the Gateway Setup Editor by adding the following configuration in Dynamic Entities > Collectors. The available collector for the JDBC plugin is
JdbcCollector. For more information on how to set up your collectors, see Collectors in Dynamic Entities.For more information, see Collectors in Dynamic Entities. - Add the configuration to the
collection-agent.ymlfile on your local machine.
Configure your mappings Copied
To display metrics in Geneos, configure Dynamic Entity mappings and attach them to the Netprobe that receives data from the Collection Agent.
You can configure mappings using one of the following options:
- Add the provided
jdbc_mapping.xmlas an include file in your Gateway. This provides JDBC Generic Query, which expects:
| Dimension | In collector | Geneos |
|---|---|---|
database |
dimensions.static |
Entity |
table |
dimensions.static |
Dataview |
row_key |
dimensions.dbColumns |
Row |
Alias the row ID in SQL (for example, SELECT username AS row_key, ...). Example:
dimensions:
  dbColumns:
    - row_key
  static:
    table: "users"
    database: "mydatabase"
- Set up a custom mapping in Dynamic Entities > Mapping. For more information, see Mapping and mapping group in Dynamic Entities.